
Intermediate · visual course

AI & Machine Learning

Machine learning finds useful patterns in examples; it does not understand a problem in the same way a person does.

PythonTensorFlowData 4 guided sessions 8 skill tracks 3 example projects
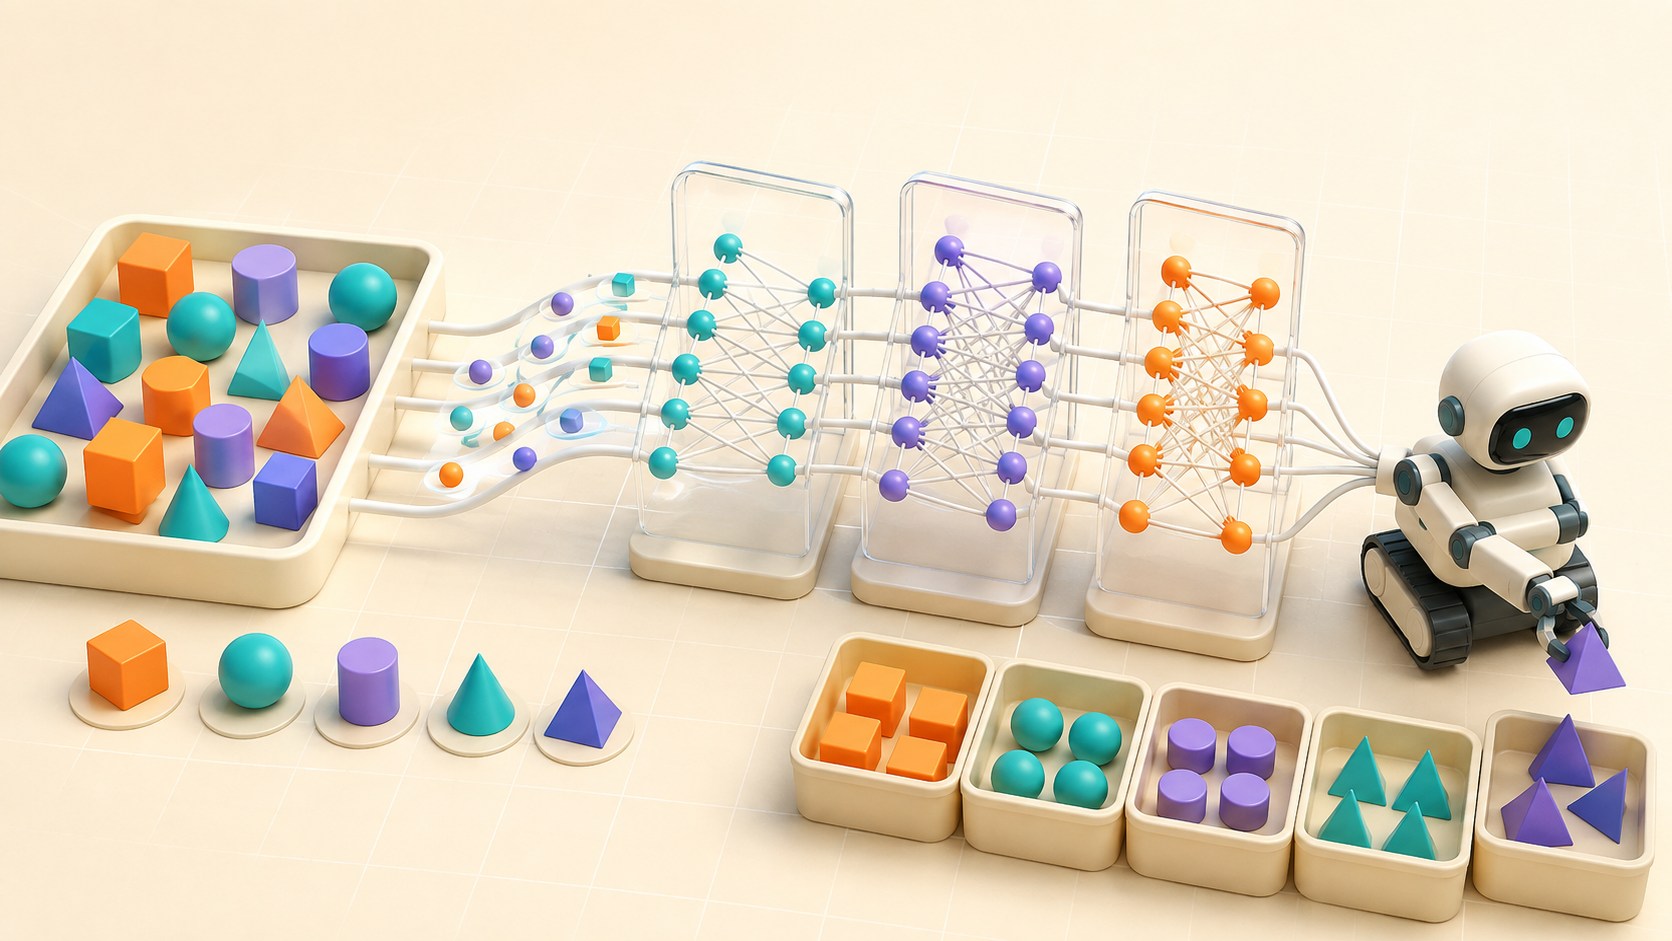
Three-dimensional machine-learning pipeline sorting colored shapes after learning from examples
Concept overview · generated for this Academy4Tech lesson
Start here

See the system, then build it.

A model can be mathematically accurate on its training data and still fail in the real world. Test the whole system.

01Identify examples, features and labels
02Separate training, validation and test data
03Explain classification and regression
04Evaluate errors, bias and safe human oversight
Your progress Keep your learning momentum going

0 of 4 sessions complete

Interactive 3D learning studio

Machine-learning studio

Trace examples through training, evaluation and a prediction decision without hiding uncertainty.

Interactive system model · loads on request Poster mode
Explore the system in 3D Inspect the labelled subsystems and watch their modelled process. The lesson flow beside it is a separate conceptual sequence unless it explicitly names the same subsystem. The poster remains available if WebGL is unsupported.
Selected lesson · conceptual flow

Learn from examples

What does a machine-learning model actually learn?

Step 1 of 4 · Examples

Step through this lesson’s conceptual sequence here. Inspect the separate 3D subsystem model below it to understand the system’s structure.

3D subsystem inspector · 4 model parts
Mini experiment

Change one variable. Predict first, then test.

Choose a review threshold from 65% to 80%.

65%
Live result Move the control to test your prediction

Choose a review threshold from 65% to 80%.

Every highlighted 3D group corresponds to a labelled system part. A slider changes the model only when that relationship can be represented faithfully; otherwise the geometry stays still and the live calculation explains the effect. The model simplifies scale and geometry, so use the lesson’s safety notes, measurements and official documentation when building a real system.

01
Session 1 · 20 min

Learn from examples

What does a machine-learning model actually learn?

Understand it

A dataset contains examples. Features describe each example, and a label is the answer for supervised learning. Training adjusts model parameters so inputs map to useful outputs. The model learns statistical patterns, including unwanted patterns in poor data.

Interactive concept flow

Step 1 of 4 Examples

Choose a step to inspect it, or run the complete sequence.

Sequence progress
1 / 4
Picture it

A useful analogy

Sorting many objects by examples can reveal a rule, but a misleading set of examples teaches the wrong rule.

Apply it

Worked example

Use colour and weight as features to classify recyclable objects, while checking that the background does not accidentally reveal the label.

Try it
  1. Choose a simple classification task.
  2. Write two useful features and one misleading feature.
  3. Explain how you would label ten examples.
Quick checkWhat is a label?

Answer: It is the target answer associated with a training example in supervised learning.

02
Session 2 · 25 min

Train, validate and test

How do we know a model learned a pattern instead of memorising?

Understand it

Training data adjusts the model. Validation data helps choose settings. Test data estimates performance on unseen examples and must not guide training. Overfitting happens when a model matches training details but performs poorly on new data.

Interactive concept flow

Step 1 of 4 Training set

Choose a step to inspect it, or run the complete sequence.

Sequence progress
1 / 4
Picture it

A useful analogy

Practise questions teach you, a mock exam guides revision, and a sealed final exam measures what transfers.

Apply it

Worked example

Split plant images by individual plant, not random near-identical frames, so the test set is genuinely new.

Try it
  1. Divide 20 paper examples into three sets.
  2. Keep the test labels hidden while making a rule.
  3. Measure the final unseen result once.
Quick checkWhy keep test data separate?

Answer: Using it to tune the model would make the final score overly optimistic.

03
Session 3 · 25 min

Predictions and metrics

Which score tells us whether a model is useful?

Understand it

Regression predicts a number; classification predicts a category or probability. Accuracy alone can mislead when one class is rare. A confusion matrix separates true positives, false positives, true negatives and false negatives so the cost of each error is visible.

Interactive concept flow

Step 1 of 4 Prediction

Choose a step to inspect it, or run the complete sequence.

Sequence progress
1 / 4
Picture it

A useful analogy

A fire alarm that never rings is correct most of the time but useless when fire is rare.

Apply it

Worked example

For a safety detector, missing a hazard may cost more than a false alarm, so recall may matter more than overall accuracy.

Try it
  1. Create a 2×2 confusion matrix for ten predictions.
  2. Count false alarms and missed cases.
  3. Decide which error matters most for your task.
Quick checkWhen can high accuracy be misleading?

Answer: When one class is much more common, a model can ignore the rare class and still appear accurate.

04
Session 4 · 30 min

Responsible deployment

What should happen before people depend on a model?

Understand it

Test data quality, different user groups, unusual conditions and changes over time. Explain the model’s limits, monitor failures and provide human review for meaningful decisions. Protect private data and make it possible to stop or replace the model.

Interactive concept flow

Step 1 of 4 Test broadly

Choose a step to inspect it, or run the complete sequence.

Sequence progress
1 / 4
Picture it

A useful analogy

A new team member needs a clear job, supervision, feedback and limits—not blind trust.

Apply it

Worked example

A school recycling assistant suggests a bin but lets the student correct it; corrections are reviewed before any retraining.

Try it
  1. Write a model card for your classifier.
  2. List intended use, two limits and one group it may underserve.
  3. Add a human override and monitoring signal.
Quick checkWhy monitor a deployed model?

Answer: Real-world data and conditions change, so performance can decline or new harms can appear.

Beyond the guided sessions

Explore the whole AI & Machine Learning field

The guided sessions teach the foundations. This map widens the view across 8 important tracks, with explanations, practice prompts, knowledge checks, and official sources for deeper study.

Understand how AI learns from data, how major model families work, and how to evaluate, govern, secure, and operate them responsibly.

Field map 0 of 8 tracks explored
Open a track to add it to your journey.
  1. Foundation AI foundations
    Track overview

    AI systems perform defined tasks through rules or learned statistical patterns, but their outputs remain limited by objectives, data, context, and uncertainty.

    Core concepts

    Four ideas to understand

    1. rules versus learning

      A rule-based system follows instructions written by people, while machine learning fits behavior from examples or feedback. Many useful systems combine both, using rules for hard constraints and models for uncertain patterns.

    2. features and labels

      Features are inputs supplied to a model, and a label is a target answer used in supervised learning. The chosen representation determines which patterns the model can access.

    3. training and inference

      Training adjusts model parameters using data and an objective; inference applies the fixed learned parameters to new inputs. These phases can have very different compute, latency, and privacy requirements.

    4. capabilities and limits

      Benchmark performance does not guarantee correct output for every person, place, or future condition. State the intended use, uncertainty, known failure modes, and situations requiring human judgment.

    Check your thinking What changes during model training?
    Answer

    The model parameters are adjusted to improve an objective on training data.

  2. Foundation Data readiness
    Track overview

    Model quality begins with lawful, representative, well-documented data and a split strategy that prevents evaluation leakage.

    Core concepts

    Four ideas to understand

    1. collection and provenance

      Provenance records where data came from, why it was collected, consent or license conditions, and how it changed. Without it, quality, rights, and reproducibility are hard to assess.

    2. cleaning and encoding

      Cleaning handles missing, duplicated, inconsistent, or impossible records, while encoding turns categories or text into model-ready values. Fit data-dependent transforms only on training data.

    3. sampling bias

      A sample is biased when it represents some relevant groups or conditions differently from the intended population. More data does not fix a systematic coverage gap.

    4. train-validation-test split

      Training data fits parameters, validation data guides choices, and test data estimates final performance. Related people, times, or locations may need group-aware splits to prevent hidden leakage.

    Check your thinking Why should the test set remain untouched during model selection?
    Answer

    Repeated choices based on it would tune the system to the test data and make the final estimate too optimistic.

  3. Foundation Learning mathematics
    Track overview

    Vectors represent examples and parameters, probability represents uncertainty, loss measures error, and optimization searches for better parameters.

    Core concepts

    Four ideas to understand

    1. vectors and matrices

      A vector stores an ordered set of features or parameters, while a matrix organizes many examples or a linear transformation. Shape compatibility explains which operations are meaningful.

    2. probability

      Probabilities quantify uncertainty under a model and must lie between zero and one. A score may still rank cases when uncalibrated, but it should be interpreted as a probability only when observed frequencies match its claimed confidence on intended data.

    3. loss functions

      A loss assigns a cost to prediction error so training has an objective to reduce. The selected loss encodes priorities and may not match the real-world harm of every mistake.

    4. gradient descent

      Gradient descent changes parameters opposite the local loss gradient, scaled by a learning rate. Steps that are too large can diverge, while tiny steps can learn slowly or stall.

    Check your thinking What does the gradient indicate during optimization?
    Answer

    It indicates the local direction and rate of greatest increase in loss, so descent moves the other way.

  4. Applied Supervised learning
    Track overview

    Supervised models learn from labeled examples to predict categories or numeric values, with complexity controlled to support generalization.

    Core concepts

    Four ideas to understand

    1. linear models

      A linear model combines features with learned weights and an intercept. It is fast and interpretable but needs suitable features when relationships are nonlinear.

    2. decision trees

      A decision tree splits examples using feature rules until reaching predictions. Deep trees can memorize training details, so depth, minimum samples, pruning, or ensembles control variance.

    3. classification

      Classification predicts a discrete class or class probability. Decision thresholds should be chosen from the cost of false positives and false negatives, not accuracy alone.

    4. regression

      Regression predicts a continuous quantity such as demand or temperature. Evaluate error magnitude and distribution, including performance on important ranges and groups.

    Check your thinking Why can a very deep decision tree perform well on training data but poorly on new data?
    Answer

    It can overfit details and noise that do not generalize beyond the training examples.

  5. Applied Discovery and decisions
    Track overview

    Unsupervised methods organize unlabeled data, anomaly methods flag unusual cases, and reinforcement learning studies sequential decisions and rewards.

    Core concepts

    Four ideas to understand

    1. clustering

      Clustering groups examples by a chosen similarity and algorithm rather than discovering guaranteed real-world categories. Scale features, test stability, and interpret clusters with domain evidence.

    2. dimensionality reduction

      Dimensionality reduction represents data with fewer variables for compression, denoising, modeling, or visualization. A two-dimensional plot can distort distances and should not become proof of separation by itself.

    3. anomaly detection

      Anomaly detection ranks observations unlike an expected pattern, but unusual does not automatically mean harmful. Thresholds need labeled review, changing baselines, and a plan for false alarms.

    4. reinforcement learning

      An agent observes a state, takes actions, and learns from rewards over time. Reward design, exploration, delayed effects, simulation gaps, and safe constraints make real deployment difficult.

    Check your thinking Why can an agent maximize reward yet behave incorrectly?
    Answer

    A reward is only a proxy for the intended goal, so the agent may exploit an omission unless behavior and constraints are tested separately.

  6. Advanced Neural and generative AI
    Track overview

    Neural networks learn layered representations, while transformer-based generative systems predict new content and need grounding, safeguards, and verification.

    Core concepts

    Four ideas to understand

    1. neural networks

      Layers apply learned transformations and nonlinear activations to build increasingly useful representations. Training uses backpropagation to compute gradients, while regularization and validation help control overfitting.

    2. transformers and foundation models

      Transformers stack attention and feed-forward layers, with position information added because attention alone does not encode order. Large-scale pretraining can produce foundation models that adapt across tasks and, in multimodal systems, connect text, images, audio, or other inputs.

    3. generative models

      A generative model learns a distribution and samples text, images, audio, or other data from it. Fluent output can still be false, unsafe, copied, biased, or inconsistent because generation is not fact verification.

    4. retrieval, agents, and tools

      Retrieval can add external evidence, while an agent can plan repeated model and tool calls toward a goal. Treat all retrieved content as untrusted, enforce narrow permissions and budgets, require confirmation for consequential actions, preserve traces, and verify important outputs.

    Check your thinking Does adding retrieval guarantee that a generated answer is correct?
    Answer

    No; retrieval can be irrelevant or malicious, and the model can still misread or invent claims, so verification remains necessary.

  7. Advanced Evaluation and responsibility
    Track overview

    Responsible evaluation connects technical metrics to affected people, operating conditions, transparency, oversight, and documented risk treatment.

    Core concepts

    Four ideas to understand

    1. precision and recall

      Precision asks how many predicted positives were correct; recall asks how many actual positives were found. Threshold and class prevalence affect both, so report the metric tied to the real error costs.

    2. robustness and calibration

      Robustness tests performance under noise, shift, misuse, or attack, while calibration checks whether confidence matches observed correctness. Stress tests should include plausible worst cases, not only average data.

    3. fairness and impact

      Aggregate accuracy can hide different error rates or harms across groups and contexts. Involve affected people, examine relevant slices, and avoid treating a single fairness metric as a complete ethical decision.

    4. explainability and oversight

      Explanations should answer a real audience question and be tested for faithfulness and usefulness. High-impact systems need qualified human review, appeal, traceability, and authority to pause or override automation.

    Check your thinking What is recall for a positive class?
    Answer

    The number of correctly predicted positives divided by all actual positives.

  8. Advanced Production AI
    Track overview

    Production AI is a monitored sociotechnical system with versioned data and models, secure interfaces, rollback, privacy controls, and accountable retirement.

    Core concepts

    Four ideas to understand

    1. deployment and TEVV

      Version the model, code, data schema, configuration, and evaluation evidence as one release. Use test, evaluation, verification, and validation tied to the intended context, then monitor health, inputs, outcomes, incidents, and rollback readiness.

    2. data and concept drift

      Data drift changes the input distribution, while concept drift changes the relationship between inputs and the desired answer. Drift signals investigation and re-evaluation; it does not by itself prove retraining is safe.

    3. security and supply chains

      Track the provenance and integrity of data, models, dependencies, and external services. Minimize personal data, control access, and test poisoning, evasion, extraction, prompt-based abuse, compromised components, and sensitive logs where relevant.

    4. resource and life-cycle impact

      Measure latency, energy, hardware, cost, and environmental impact across training and repeated inference. Define ownership, update support, incident response, and conditions for disabling or retiring the system.

    Check your thinking What is the difference between data drift and concept drift?
    Answer

    Data drift changes input patterns; concept drift changes how inputs relate to the correct outcome.

Verified next steps

Official references

Use these primary sources to extend the explanations and check current guidance.

  1. Google for Developers Machine Learning Crash Course
  2. scikit-learn project User Guide
  3. PyTorch Foundation Learn the Basics
  4. Google Research Attention Is All You Need
  5. National Institute of Standards and Technology AI Risk Management Framework and current updates
  6. National Institute of Standards and Technology Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile
  7. National Institute of Standards and Technology TEVV-Athlon Framework for Evaluating AI Systems — Initial Public Draft
  8. Organisation for Economic Co-operation and Development AI Principles Overview
  9. United Nations Educational, Scientific and Cultural Organization Ethics of Artificial Intelligence
Three-project build pathway

Learn AI & Machine Learning by making it work.

Start small, combine the ideas, then complete a measured challenge. Every project includes a material list, four build milestones, evidence to collect, and a safe next step.

  1. Starter · 60–90 minutes Rules versus a Tiny Model Learn one dependable building block Use a small synthetic fruit dataset to compare a hand-written sorting rule with a simple classifier. Learners inspect errors and discover that a model learns patterns from examples rather than understanding fruit.
    What you will learn

    Learning goals

    • Separate features, labels, training, prediction, and evaluation.
    • Keep training and test examples separate and explain why leakage gives misleading results.
    • Interpret individual errors and uncertainty without describing a prediction as certain or intelligent.
    Prepare

    Materials and tools

    • Browser notebook or Python with a beginner-friendly ML library
    • Provided synthetic fruit table with colour, mass, texture, and fictional label
    • Train/test split worksheet
    • Confusion-matrix template
    Build sequence

    Four milestones

    1. Inspect the synthetic examples, define each feature and label, and write one simple sorting rule.

    2. Split data before fitting, train a small classifier, and record predictions on untouched test rows.

    3. Compare rule and model errors with a confusion matrix and inspect at least three misclassified examples.

    4. Change one data assumption, rerun evaluation, and write a short model-purpose and limitation statement.

    Prove it works

    Evidence to collect

    • The notebook keeps test rows out of training and can reproduce the split with a documented seed.
    • Metrics include the test-set size and class counts, not only a single accuracy number.
    • The conclusion names a concrete failure pattern and avoids claiming that the model understands real fruit.
  2. Builder · 2–3 hours Transparent Recycling Sorter Connect multiple ideas into a working system Train and audit a tabular model that recommends one of several fictional recycling bins from synthetic material properties, with an abstain option and a model card that clearly limits the result to the classroom dataset.
    What you will learn

    Learning goals

    • Build a reproducible preprocessing, training, validation, and test pipeline.
    • Compare per-class precision and recall and use a confidence threshold for review.
    • Document intended use, data provenance, evaluation conditions, limitations, and human oversight.
    Prepare

    Materials and tools

    • Python notebook with scikit-learn or equivalent browser tool
    • Provided synthetic recycling dataset and data dictionary
    • Model-card and risk-assessment templates
    • Metric plots and error-analysis worksheet
    Build sequence

    Four milestones

    1. State the narrow task, harm of each error type, abstain behavior, data fields, and excluded real-world uses.

    2. Create reproducible train, validation, and test partitions and a pipeline that fits preprocessing only on training data.

    3. Compare two simple models using per-class metrics, confusion matrices, threshold curves, and difficult examples.

    4. Choose a review threshold, test missing and shifted values, and publish a model card alongside the selected artifact.

    Prove it works

    Evidence to collect

    • The final evaluation runs once on untouched test data and reports per-class results with sample counts.
    • Every low-confidence or invalid input is routed to review instead of being presented as an assured answer.
    • The model card identifies synthetic provenance, intended users, excluded uses, known failure cases, version, and monitoring plan.
  3. Challenge · 4–6 hours Human-Review Help-Request Router Test, measure, and improve a complete solution Build a local prototype that routes invented help requests to fictional support categories, explains its uncertainty, abstains when appropriate, and lets a reviewer correct results. The objective is a testable human-in-the-loop system, not an autonomous authority.
    What you will learn

    Learning goals

    • Design evaluation around errors, subgroups of scenarios, abstention, and human override.
    • Treat data governance, privacy, model limitations, misuse, monitoring, and change control as engineering requirements.
    • Red-team ambiguous, out-of-scope, adversarial, and prompt-like inputs without assuming one test proves safety.
    Prepare

    Materials and tools

    • Local Python or browser ML environment
    • Learner-authored fictional requests with no names, contact details, or real cases
    • Baseline classifier or embedding model suitable for offline prototyping
    • Review interface, model card, data sheet, and test matrix templates
    Build sequence

    Four milestones

    1. Define categories, excluded high-stakes uses, privacy rules, reviewer authority, error harms, and measurable release criteria.

    2. Create versioned fictional data partitions, baseline routing, calibrated or ranked scores, abstention, and an audit record.

    3. Build a review queue where humans can accept, correct, or reject suggestions without exposing hidden answer keys.

    4. Run normal, ambiguous, shifted, malformed, adversarial, and subgroup scenario suites; document failures and a monitoring response.

    Prove it works

    Evidence to collect

    • The evaluation reports routing quality, abstention coverage, error types, and scenario-group results with uncertainty and sample counts.
    • Out-of-scope, malformed, and low-confidence requests reliably enter human review and no model output bypasses reviewer authority.
    • A complete model card and risk record describe provenance, versions, controls, limitations, misuse cases, unresolved risks, and rollback criteria.
Words to know

Build your vocabulary.

Feature
An input measurement used by a model.
Label
The target answer for a supervised example.
Training
Adjusting model parameters using examples.
Overfitting
Learning training details that do not generalise.
Classification
Predicting a category or class probability.
Regression
Predicting a numeric value.
Keep studying

Official documentation.

These lessons simplify the first ideas. Use the original documentation when building, checking details or moving to the next level.

Continue learning

Related Academy4Tech content.

Learn by building.

Choose a real project, identify the smallest subsystem you can test, and document what the measurement tells you.